MariaDB versus MySQL versus PostgreSQL benchmark

MariaDB vs MySQL vs PostgreSQL: an mpazari Benchmark

I recently compared MariaDB, MySQL, and PostgreSQL using the real mpazari.com application. The goal was not to produce a synthetic database benchmark. I wanted to answer a more practical question: does MariaDB really have an advantage when an application sends many simple queries? This question came up after reading an argument that PostgreSQL is obviously faster than MySQL, but that MariaDB should be faster for applications with many simple queries, while PostgreSQL is probably better for complex joins. The suggestion was that a MariaDB versus PostgreSQL comparison would be more interesting than a PostgreSQL versus MySQL comparison. ...
September 23, 2026 · 6 min · Özkan Pakdil
java spring to rust warp

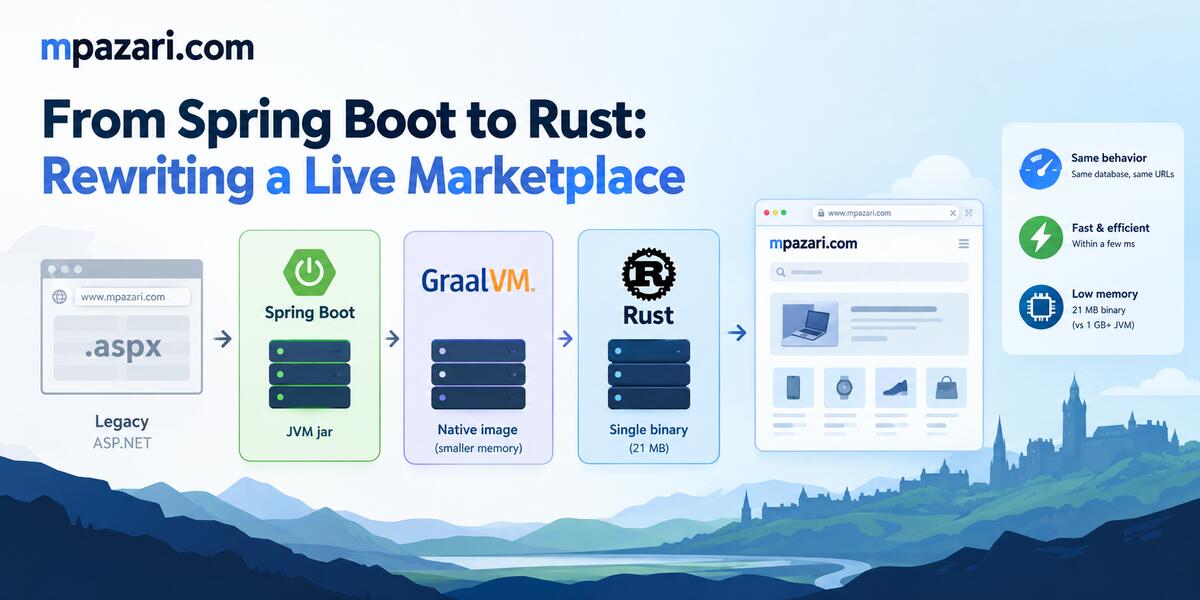
From Spring Boot to Rust: Rewriting a Live Marketplace

From Spring Boot to Rust: Rewriting a Live Marketplace mpazari.com spent years on a legacy ASP.NET stack — the .aspx URLs still in the wild prove it. A recent Spring Boot rewrite replaced that engine, first as a JVM jar, then as a GraalVM native image to tame memory usage. The question that started this project: if we rewrote the whole application in Rust, what would we gain, what would we break, and how do we prove we broke nothing? This post covers the rewrite, the parity hunting, the server-side build/deploy pipeline, and the load test comparing all three runtimes on the same production box. ...

September 21, 2026 · 5 min · Özkan Pakdil
Vulkan acceleration on Debian

Accelerating LLMs on Debian 13: Setting up Vulkan for llama.cpp

After setting up CUDA on my other laptop, I moved to a different(older) machine that doesn’t have an NVIDIA GPU. This one is an everyday laptop with integrated Intel graphics, but that doesn’t mean we have to settle for slow CPU-only performance. On this machine, I switched to the Vulkan backend for llama.cpp and the results were even more dramatic than I expected. Machine Hardware Info This laptop is running Debian 13 (Trixie/Sid) with the following specs: ...

March 22, 2026 · 3 min · Özkan Pakdil
NVIDIA CUDA acceleration on Debian

Accelerating LLMs on Debian 13: Setting up CUDA for llama.cpp

Setting up NVIDIA CUDA on Debian 13 (Trixie/Sid) to run Large Language Models (LLMs) can be a bit of a journey, especially if you’re transitioning from the default open-source drivers to the proprietary stack required for GPGPU workloads. Over the last few days, I’ve been working on getting llama.cpp to run with CUDA on my laptop to see how much of a difference it makes compared to pure CPU execution. ...

March 20, 2026 · 7 min · Özkan Pakdil
Podman performance optimization on macOS

Tuning Podman on macOS to Match OrbStack Performance

Note: These are suggested optimizations I have not personally tried yet. I’m blogging them as I’m planning to test them throughout this week. OrbStack is highly optimized for macOS, using a proprietary, high-performance networking stack and a custom VirtioFS implementation with aggressive caching. Podman, while being open-source and standard-compliant, can be tuned to significantly bridge the performance gap. The following plan outlines key areas where Podman’s performance can be improved on macOS: ...

March 8, 2026 · 3 min · Özkan Pakdil